EN ES FR ID
Continuous Batching 1:05
πŸ“Ί AI Guru β€’ πŸ‘οΈ 1 view
What is Continuous Batching 2:52
πŸ“Ί Standarity β€’ πŸ‘οΈ 12 views

Continuous Batching Ai S Engine Information Guide

  1. Overview on Continuous Batching Ai S Engine
  2. Important Facts
  3. Recent Updates
  4. Expert Insights
  5. Final Thoughts

Overview on Continuous Batching Ai S Engine

Details How to Scale LLM Applications With Continuous Batching! News
Looking for the latest information on Continuous Batching Ai S Engine? We've gathered comprehensive data, records, and insights about Continuous Batching Ai S Engine.

Important Facts

Information Gentle Introduction to Static, Dynamic, and Continuous Batching for LLM Inference Update
Explore the key sources for Continuous Batching Ai S Engine.

Recent Updates

Continuous Batching - How LLM Servers Keep the GPU Full Update
Stay updated on Continuous Batching Ai S Engine's newest achievements.

Continuous Batching: Optimize LLM Serving Throughput and Latency
Continuous Batching
Continuous Batching
What is Continuous Batching
LLM Optimization Lecture 5: Continuous Batching and Piggyback Decoding
Continuous Batching Explained: Iteration-Level Scheduling in vLLM (Orca Paper)
NVIDIA TensorRT-LLM GitHub Tutorial: Continuous Batching, KV Cache, and GPU Optimization
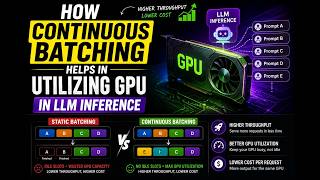
How Continuous Batching Helps In Utilizing GPU In LLM Inference | LLM | Batching
Noob Vibe Learning: Continuous batching
LLM Inference Optimization: Async Continuous Batching with CUDA Streams
Continuous Batching vLLM: Kyun Har Jawab Alag Hota Hai
GitHub - jundot/omlx: LLM inference server with continuous batching & SSD caching for Apple Silic...

Expert Insights

Data is compiled from public records and verified media reports.

Last Updated: September 14, 2026

Final Thoughts

Details LLM Inference Engines: vLLM,  KV Cache, Paged attention and Continuous Batching. Update
For 2026, Continuous Batching Ai S Engine remains one of the most talked-about information profiles. Check back for the newest reports.

Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.

Advertisement